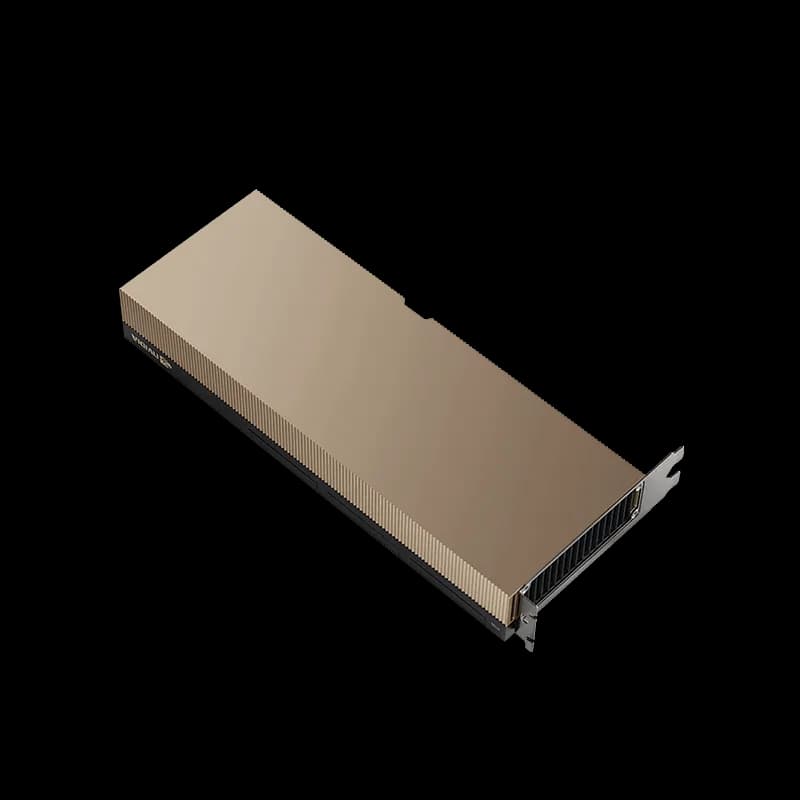
NVIDIA H100 PCIe 80GB
$25,000 – $33,000
NVIDIA H100 PCIe 80GB with HBM2e memory — the Hopper architecture GPU for AI training and inference. Transformer Engine with FP8 support delivers 3x the AI performance of A100 on compute, though its 2 TB/s of memory bandwidth is marginally below the A100 80GB's 2,039 GB/s. The standard for production LLM serving and model training.
Affiliate links — We earn a commission on qualifying purchases at no cost to you.
Specifications
| VRAM | 80GB HBM2e |
| Tensor Cores | 456 (4th Gen) |
| Memory Bandwidth | 2,000 GB/s |
| TDP | 350W |
| Interface | PCIe 5.0 x16 |
Pros
- 3x AI performance over A100
- Transformer Engine for FP8 precision
- Industry-standard for production AI
Cons
- Extremely expensive ($25K+)
- Requires enterprise infrastructure
- Long lead times on orders
Related Articles
DeepSeek V4-Flash Local Hardware Guide 2026 — What It Actually Takes to Run a 284B MIT-Licensed MoE
DeepSeek V4-Flash dropped April 24 under MIT license: 284B total / 13B active, 1M context, Claude Haiku-tier API pricing. Here's what hardware actually runs it locally — five priced buyer paths from $5,999 Mac Studio to $11K RTX PRO 6000, the 90 GB don't-bother cutoff, and why the MoE active-parameter math reframes every decision.
How to Run Kimi K2.6 Locally (2026): The Real Hardware It Takes — and the Cheapest Rig That Actually Works
Kimi K2.6 (Moonshot AI, April 2026) is the leading open-weight coding model — a 1.04T-parameter MoE with 32B active. Here's the honest answer: you basically can't run it on one card. Full per-quant memory table (Q2→FP16), the cheapest rig that fits (4× RTX 3090 + 256GB RAM ≈ 350GB), the 8×H200 money-no-object path, and a clean offramp to smaller models if your box can't reach 350GB.
Related Products
Disclosure: Some links on this page are affiliate links. We may earn a commission if you make a purchase — at no extra cost to you. This helps support our independent reviews.